Skip to content
-
Kustomiz-it

DIY-Projects-UNIX-Software-Hardware-Cars

  • Home
  • Privacy Policy
  • Home
  • Privacy Policy

AI

Run Qwen3.8-27B in 8-12 GB With GSQ-RCO Non-Uniform GGUF Quantizations

Run Qwen3.8-27B in 8-12 GB With GSQ-RCO Non-Uniform GGUF Quantizations

Posted by By Alber 2026-09-26
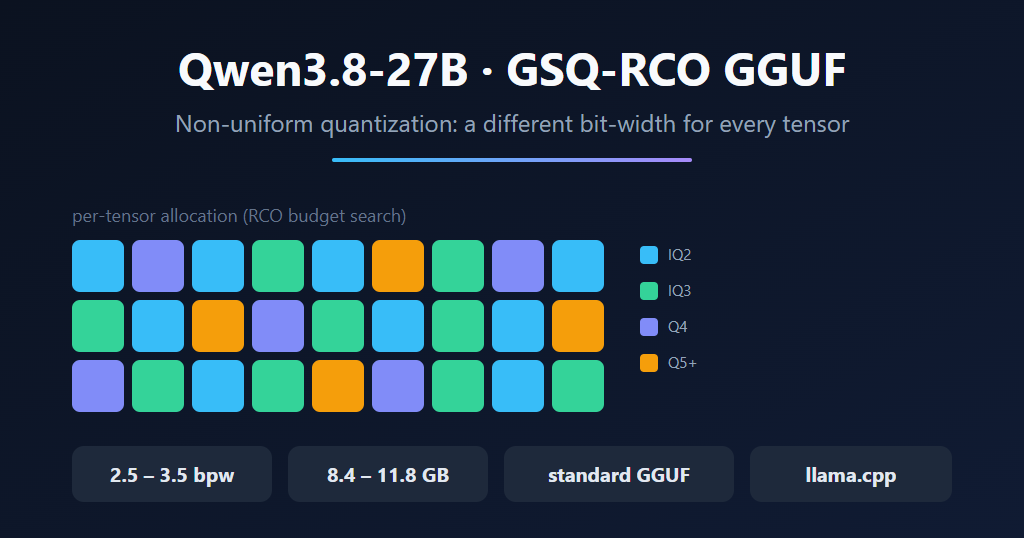
Non-uniform (mixed-precision) GGUF quantizations of Qwen3.8-27B from the IST Austria DAS Lab, built with GSQ and RCO. The smallest file is 8.4 GB and already beats BF16 on zero-shot tasks; the 11.8 GB variant is task-lossless. Standard GGUF that runs in llama.cpp, Ollama and LM Studio.
Read More
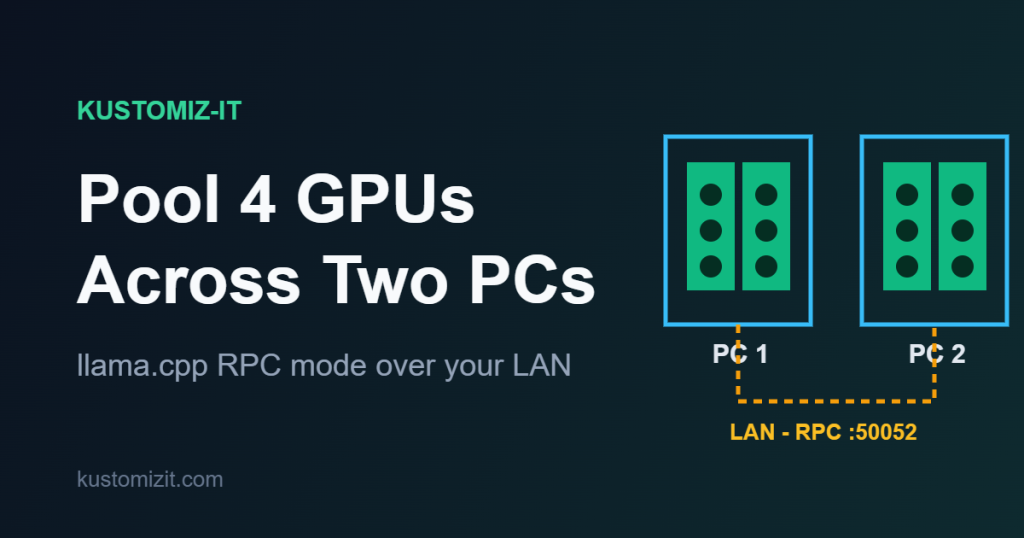
Diagram of two PCs connected over a LAN, each with two RTX 3060 GPUs, pooled via llama.cpp RPC

Pool 4 GPUs Across Two PCs With llama.cpp RPC Mode

Posted by By Alber 2026-09-15
You don’t have to pick just one machine to run your model on. If you have two PCs with GPUs on the same network, llama.cpp can use all of them…
Read More
Build llama.cpp from Source CUDA Ubuntu Server

Build llama.cpp from Source – CUDA – Ubuntu Server

Posted by By Alber 2026-05-17
While you can download pre-built binaries, building from source is the best way to ensure you have the latest optimizations, full support for your specific hardware (especially if you are…
Read More
Copyright 2026 — Kustomiz-it. All rights reserved. Bloglo WordPress Theme
Scroll to Top imunify-bot-check