

Run Qwen3.8-27B in 8-12 GB With GSQ-RCO Non-Uniform GGUF Quantizations
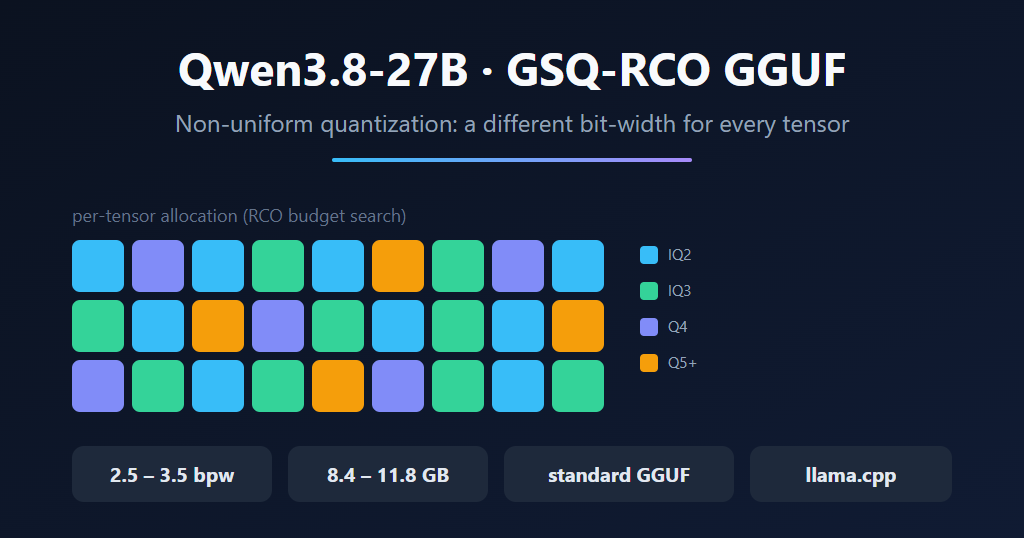
Non-uniform (mixed-precision) GGUF quantizations of Qwen3.8-27B from the IST Austria DAS Lab, built with GSQ and RCO. The smallest file is 8.4 GB and already beats BF16 on zero-shot tasks; the 11.8 GB variant is task-lossless. Standard GGUF that runs in llama.cpp, Ollama and LM Studio.