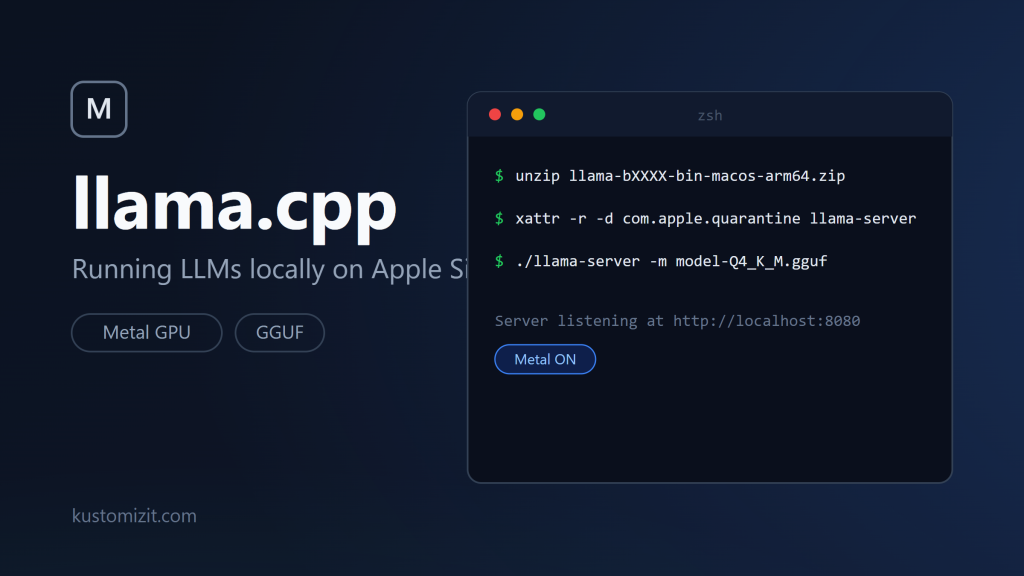
Running llama.cpp on an Apple Silicon Mac: A Simple Guide

llama.cpp is a lightweight C/C++ port of LLM inference that runs great on Apple Silicon, using the GPU through Metal. Here is the fastest way to get a local model…
DIY-Projects-UNIX-Software-Hardware-Cars